TL;DR
An LLM Wiki is a folder of interlinked markdown files that a Claude Code agent compiles from sources you feed it and maintains through three operations: ingest, query, and lint. No vector database, no embedding pipeline. Karpathy introduced the pattern in April 2026; his gist carries 5,000+ stars
Roughly 64% of developers spend 30+ minutes a day searching for answers they already found once, per a 28,911-respondent 2024 developer survey (Statista, 2024)
Since May: Claude Code shipped auto memory (they compose, they don't compete), Platformer built a 1,440-page wiki from a 16-year archive, and the pattern now ships as a packaged skill in other agent stacks
By the end of this guide you'll have a working LLM Wiki with a real CLAUDE.md schema and your first ingested source, in Claude Code or, with no terminal at all, in Claude Cowork
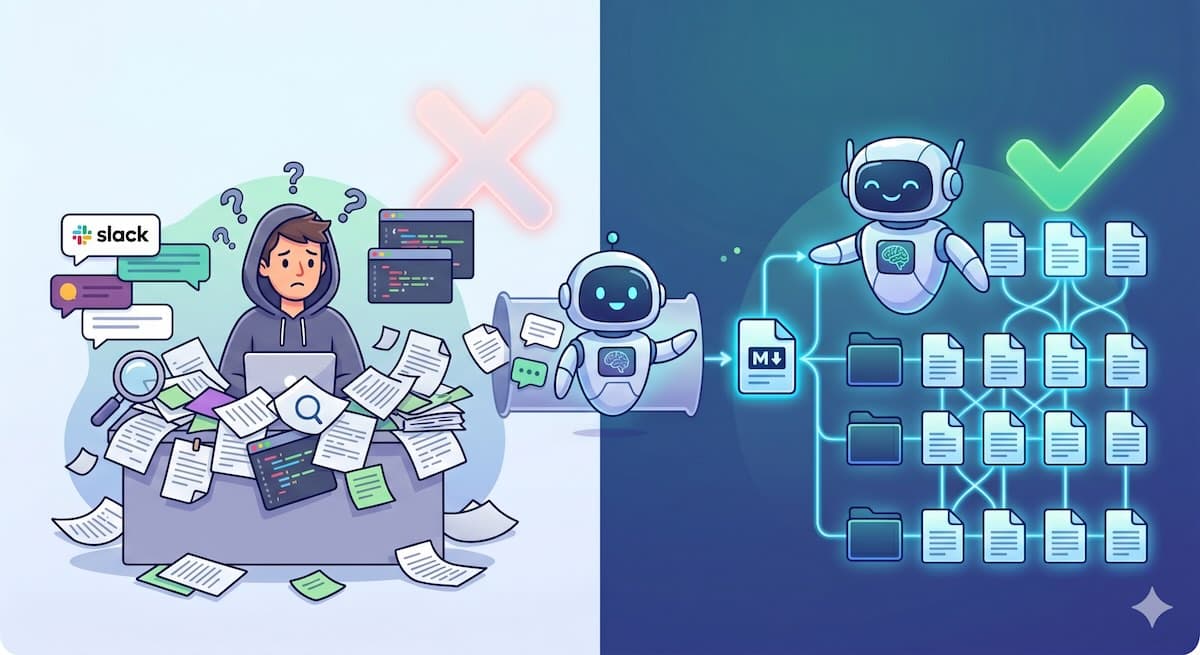
Roughly 64% of developers spend more than 30 minutes a day searching for answers to problems they've already solved, according to a 2024 survey of 28,911 developers (Statista, 2024). You know the feeling. Someone asks about that thing you figured out three months ago, and you're digging through Slack threads, Notion pages, and your own brain trying to reconstruct it.
Karpathy dropped a gist on April 4, 2026, that fixes this. His LLM Wiki pattern turns your Claude Code agent into a personal librarian that reads everything you throw at it, builds a structured wiki, and keeps it up to date. No RAG pipeline. No vector database. No DevOps hell.
Five months on, practitioners have stress-tested the pattern well beyond the gist, and Claude Code itself has changed underneath it. This guide is updated for both. Here's what an LLM Wiki is, why it beats the alternatives, and exactly how to build one, whether you live in a terminal or you'd rather never open one.
What the Hell is an LLM Wiki?
An LLM Wiki is a folder of interlinked Markdown files that your agent compiles from sources you feed it, governed by one schema file. Karpathy's gist introducing the pattern has collected 5,000+ stars and thousands of forks since April 2026, and its comment thread has become the pattern's de facto ecosystem hub.
Instead of dumping documents into a vector database and hoping RAG finds the right chunk, your LLM reads sources once and compiles what it learns into a permanent, interlinked markdown wiki.
Three layers. That's it.
Raw Sources at the bottom. These are articles, papers, PDFs, transcripts. Whatever you feed the system. The LLM reads them but never touches the originals.
The Wiki in the middle. This is where the compounding happens: entity pages for every tool, person, and company. Concept pages for ideas and patterns. Source summaries. Cross-reference links between everything. The LLM owns this layer completely. You don't write wiki pages. You tell it what sources to digest.
The schema on top. A single CLAUDE.md file that tells your agent how to structure pages, format links, and run the three core operations: Ingest, Query, and Lint.

Nothing in those three layers is code-specific. An entity page can be a vendor, a concept page, your renewal process, a source, or a pricing email. If you run RevOps at Acme Corp, your wiki holds CRM field conventions, vendor quirks, and campaign post-mortems; the agent doesn't care that none of it compiles. It reads like developer tooling and works like a folder you own, for any kind of knowledge.
The gist's comment thread now carries local-first variants, a multi-agent continuity layer, and hard-won operational lessons from people running wikis in production. Casey Newton built one at Platformer from a 16-year article archive: 1,440+ wiki pages, including a 12,000-word meta page with 1,300+ links, along with frank caveats that the wiki "needs more or less constant maintenance" and hallucinates when source verification is skipped. And Nous Research now ships llm-wiki as a bundled skill in its Hermes Agent. When a pattern goes from gist to packaged product feature in five months, it stops being a curiosity.
This simple idea spread while a thousand productivity apps didn't for one reason: it doesn't ask you to change your workflow. You already read things and ask questions. The wiki remembers it all.
Why RAG Sucks, and LLM Wiki Doesn't
The comparison that matters isn't a per-query price table. It's a components-you-run table. An LLM Wiki is a folder plus the agent you already pay for. A RAG pipeline is a vector database, an embedding model, a chunking strategy, a retrieval layer, and re-embedding jobs every time your documents change. That second list is infrastructure you'll still be maintaining at month six.
What you run | LLM Wiki | RAG pipeline |
|---|---|---|
Storage | A folder of markdown in git | Vector database |
Preprocessing | None; agent reads the source once | Chunking + embedding model |
Retrieval | Agent reads index.md, opens 2-5 pages | Similarity search layer |
On document change | Agent updates the affected pages | Re-embed and re-index |
You maintain | One CLAUDE.md schema | All of the above |
The cost logic follows from the architecture. You spend tokens once on ingest, when the agent reads a source and updates 10-15 wiki pages. After that, queries read the pre-compiled markdown instead of re-retrieving and re-reading raw chunks every time. Karpathy's core argument is exactly this compile-once-instead-of-retrieve-every-time inversion (Karpathy, 2026). Worth noting: no published benchmark directly measures compiled-wiki versus RAG cost per query yet, so treat specific multiples you see quoted elsewhere with suspicion. The infrastructure argument stands on its own.
Where the pattern tops out
There's an honest boundary, too. Vendor analysis from Atlan (2026, an enterprise data-catalog company with a retrieval product to sell, so weigh accordingly) puts the wiki pattern's reliable ceiling around 50,000-100,000 tokens of compiled content; past that, enterprise-scale corpora genuinely want retrieval infrastructure. For a personal or team wiki, you won't hit that ceiling for a long time, and the index.md pattern stretches it further.
For a second opinion, look at Claude Code itself: it searches your codebase agentically, reading and grepping files on demand, not through a vector index. And context windows keep growing (about 30x per year on the longest models, per Epoch AI, 2025 data), which moves the ceiling in the wiki's favor over time.
But cost and architecture aren't the real argument. The real argument is that your wiki improves over time, while RAG remains as good as your chunking strategy. When you ingest a new source into an LLM Wiki, the agent cross-references everything it already knows. It spots contradictions. It updates outdated claims. RAG adds more chunks to the pile.
Think about your last five ChatGPT conversations. Almost none of what you learned there is still retrievable. That's the problem an LLM Wiki solves.
LLM Wiki vs Claude Code Auto Memory: Do You Still Need This?
Fair question, because Claude Code now writes its own memory. Since auto memory shipped, by default, Claude Code keeps a per-repository memory directory with a MEMORY.md index (the first 200 lines or 25KB load into every session) plus topic files it reads on demand, covering your preferences, corrections, and project context (Claude Code memory docs, 2026). The agent remembers things now without being told.
So is the LLM Wiki obsolete? No, and the docs themselves point to why. Auto memory is machine-local: it lives under your home directory, it's curated by Claude rather than reviewed by you, and it is explicitly not shared across machines or checked into git (Claude Code memory docs, 2026). It's the agent's private notebook. The LLM Wiki is the published handbook: deliberate, human-reviewed, versioned in git, portable to any agent, and inheritable by a teammate or your successor.
Auto memory | LLM Wiki | |
|---|---|---|
Who curates it | Claude | You direct, Claude writes, you review |
Where it lives | Your machine, outside the repo | The repo or folder, in git |
Shared with the team | No | Yes |
Survives a machine swap | No | Yes |
Works outside Claude Code | No | Yes, it's just markdown |
They compose. Auto memory quietly handles "Izzy prefers short answers and pnpm." The wiki holds "here's everything Acme Corp knows about its renewal process, reviewed and current." A team that relies on auto memory alone has knowledge trapped on individual laptops, which is the exact problem you were trying to solve.
Claude Code has had built-in auto memory on by default since 2026: a per-repo MEMORY.md index loads into every session, with topic files read on demand (Claude Code docs). Auto memory is machine-local and never checked into git, so a shared, versioned knowledge layer like an LLM wiki remains the team-facing complement, not a redundancy.
Prerequisites
99% of developers report time savings from AI tools, with 68% saving 10+ hours per week (Atlassian Developer Experience Report, 2025). Adding an LLM Wiki compounds those savings because you no longer have to re-explain context for every new agent session. You need four things.
Claude Code CLI (any recent version), or Claude Cowork on desktop if you'd rather skip the terminal (full no-terminal path near the end of this guide)
A directory where your wiki will live (I use
~/wiki/)5 minutes for setup, 15 minutes for your first ingest
Basic familiarity with Markdown and Claude Code's CLAUDE.md convention
That's the whole list. No vector database, no embedding model, no Pinecone API key you'll forget to rotate in six months.
What We're Building
You're building on the most-adopted coding agent there is: 39% of professional developers worldwide now use Claude Code at work, 47% in the US, up from 18% in January 2026, per a JetBrains survey of 15,000+ professional developers (JetBrains Developer Ecosystem Survey, August 2026). The same research wave earlier in the year measured the highest loyalty in the category: 91% satisfaction and an NPS of 54 (JetBrains AI Pulse, 2026).

Here's what you're building on top of it: a directory of interlinked Markdown files governed by a single CLAUDE.md schema. Your Claude Code agent reads the schema on every session and knows exactly how to structure, link, and maintain the wiki.
wiki/
  CLAUDE.md          # Schema, the brain
  index.md           # Catalog of every page
  log.md             # Append-only ingest record
  lint-log.md        # Lint findings, "Last lint: <date>" on top
  entities/          # People, tools, companies, projects
    promptmetrics.md
    karpathy.md
    claude-code.md
  concepts/          # Ideas, patterns, architectures
    llm-wiki-pattern.md
    rag-vs-compiled-knowledge.md
  sources/           # One summary per ingested source
    karpathy-gist-llm-wiki.md
The schema handles three operations. Ingest takes a source and updates the wiki. Query reads the index, pulls relevant pages, and answers from compiled knowledge. Lint checks for orphan pages, contradictions, and stale content.
Step 1: Scaffold Your Wiki Directory
The first step takes 30 seconds.
bash
mkdir -p ~/wiki/{entities,concepts,sources}
touch ~/wiki/index.md
touch ~/wiki/log.md
Flat directories beat nested hierarchies for LLM navigation. I started with a deep topic tree and watched Claude get lost trying to decide where new pages belonged. Three flat folders (entities, concepts, sources) eliminated that problem. The agent spends zero cycles on "where does this go" and all its cycles on content.
Seed your index.md with a placeholder:
markdown
# Wiki Index

## Entities
*(people, tools, companies, projects)*

## Concepts
*(ideas, patterns, architectures)*

## Sources
*(one summary per ingested source)*
Your log.md starts empty. It's append-only. Every ingest, query result, and lint run gets a timestamped entry. You'll never read it directly, but your agent uses it to understand what changed and when.
An LLM wiki needs exactly three flat folders (entities, concepts, sources) plus an index and a log. Flat beats nested because agents navigate by filenames and index entries, not directory trees; Platformer's 1,440-page wiki runs on this same flat-plus-index structure (Platformer, 2026). Deep nesting adds cognitive overhead for the agent and offers you zero benefit.
Step 2: Write the CLAUDE.md That Drives Everything
76% of documentation practitioners now use AI regularly in their docs workflows, and 35% report time savings above 50% (GitBook State of Docs, 2026). This schema is what you're delegating to; it's the highest-value file in the system. If you improve anything over time, improve this file, not the individual pages.
The Full Schema
Create wiki/CLAUDE.md:
markdown
# LLM Wiki Schema

## Wiki conventions
- Entity pages in `entities/<name>.md`, one per tool, person, company, or project
- Concept pages in `concepts/<topic>.md`, one per idea, pattern, or architecture
- Source summaries in `sources/<slug>.md`, one per ingested article or document
- Every page uses an H1 matching the filename in kebab-case
- Every page has frontmatter with `created`, `updated`, and `tags`
- Use `[[wikilinks]]` for all cross-references between pages
- Update `index.md` whenever you create a new page
- Log ingests to `log.md` with timestamp and summary
- Lint findings go to `lint-log.md`, headed by `Last lint: <date>`

## Ingest workflow
When I give you a URL or file to ingest:
1. Read the source completely
2. Create or update entity pages for every named tool, person, company, or project mentioned
3. Create a concept page if the source introduces a new idea worth preserving
4. Write a source summary in `sources/<slug>.md` with the key claims and why this source matters
5. Update `index.md` with new page entries and one-line descriptions
6. Add cross-reference `[[wikilinks]]` to at least 3 existing pages from the new content
7. Log the ingest to `log.md`
8. Report what you changed: number of pages created, updated, and linked

## Query workflow
When I ask a question:
1. Read `index.md` first to see what pages are available
2. Pull the 2 to 5 most relevant pages and answer from their content
3. If you find a gap where the wiki should have an answer but doesn't, tell me and offer to research it
4. If the answer is useful enough to keep, offer to file it as a new concept or entity page
5. Never fabricate. If the wiki doesn't know something, say so

## Lint workflow
When I ask you to lint, or a session-start message says the lint is stale:
1. Broken wiki-links: any `[[target]]` where `target.md` does not exist
2. Orphan pages: any page with zero inbound `[[wikilinks]]` from other pages
3. Dated claims older than 6 months: any statement carrying a verification or as-of date more than 6 months before today
4. Contradictions: two pages making incompatible claims about the same topic
Write the findings to `lint-log.md` with `Last lint: <today's date>` at the top. Do not fix anything; only report. I review the findings and approve fixes.
What Each Section Does
Wiki conventions define the file system contract. Claude knows exactly where everything goes, so it never asks "what folder should this go in?" Entity, concept, or source. Pick one.
The Ingest workflow is an eight-step pipeline that turns raw URLs into structured pages. The load-bearing step is number 6: forcing at least three cross-references per new page automatically builds the link graph. Without this, your wiki is a pile of unrelated files.
Query workflow teaches Claude to check the index before answering. This prevents the most common failure mode: Claude inventing answers when the wiki already has the right data on a page it forgot to read.
The Lint workflow is your quality-control loop: four checks (broken links, orphans, stale dated claims, contradictions), report-only, written to lint-log.md. Claude proposes; you approve fixes. Think of it as CI for your knowledge base: a repeated automatic check that catches decay before it spreads. The Last lint: date at the top of lint-log.md matters; the catch-up mechanism in Step 5 reads it.
Drop this file in your wiki root. Claude Code sessions that open in this directory will load the schema and know how to operate your wiki. No additional configuration needed. If your setup has grown its own .claude/rules/ files or a crowded CLAUDE.md, keep the wiki schema in the wiki folder's own CLAUDE.md so it loads only when you're working there.
The operator translation: at Acme Corp, the RevOps version of this schema is identical. The entities are HubSpot, your CS platform, and your top vendors. The concepts are your renewal process, your lead-routing rules, and your discount policy. The sources are vendor emails, pricing pages, and meeting transcripts.
Step 3: Ingest Your First Source
Time to feed it. Your first ingest is the biggest token bill you'll pay; later ingests update a handful of pages instead of building from zero.
Run Your First Ingest
In Claude Code, with your wiki directory as the working directory:
You: Ingest this source: https://gist.github.com/karpathy/442a6bf555914893e9891c11519de94fWhat to Expect
When I ran this with the PromptMetrics docs as a source, Claude created 11 pages in one shot. Four entity pages for the tools and people referenced, three concept pages for the architectural patterns, a source summary, and it updated three existing pages with cross-references. Total cost was about $0.15 in API tokens. That's less than the attention I'd spend writing any of those pages myself.
What you'll see:
Created: entities/karpathy.md, entities/claude-code.md, entities/mcp-protocol.md
Created: concepts/llm-wiki-pattern.md, concepts/memex-history.md, concepts/wiki-compounding.md
Created: sources/karpathy-gist-llm-wiki.md
Updated: index.md (7 new entries), concepts/knowledge-management.md (cross-references)
Log: 2026-05-04 14:32, Ingested Karpathy LLM Wiki gist, 7 pages created, 1 page updated
Your entities/karpathy.md now has a real page with background, key contributions, and links to everything relevant. A concept page explains the three-layer architecture in detail. And index.md catalogs it all so future queries know exactly what's available.
The wiki now contains knowledge you didn't have to write down. That's the point. You didn't create entity pages for every tool mentioned in the docs. Claude did that. You just told it to ingest a source. The RevOps equivalent: forward the vendor's pricing-change email into an ingest, and the vendor's entity page, your budget concept page, and the index all update themselves.
Step 4: Query Your Wiki and File the Good Answers
Querying is where you feel the compounding. Instead of re-reading source documents, Claude reads index.md, pulls the 2 to 5 most relevant pages, and answers from compiled knowledge.
You: What are the three operations in an LLM Wiki and how do they relate to each other?Claude reads the index, finds concepts/llm-wiki-pattern.md, pulls your source summary, and answers in seconds. No web search, no re-chunking, and no "I don't have access to that information."
Here's the part Karpathy emphasized that most people skip: when an answer is good enough to keep, file it back into the wiki. Your query becomes a new page.
You: File that answer as a concept page called "llm-wiki-operations"Claude creates concepts/llm-wiki-operations.md with the answer, adds [[wikilinks]] to related pages, and updates index.md. The next time you or anyone else asks that question, the answer is pre-compiled and linked into the graph. This query-to-page loop is Karpathy's core cost inversion versus RAG: filed answers become pre-compiled pages, so future queries read instead of re-retrieving.
Most people treat their LLM Wiki as read-only after ingestion. That's like buying a notebook and never writing in it. Every good answer you file becomes permanent institutional knowledge instead of ephemeral chat history.
Step 5: Lint, Maintain, and Keep It Alive
An unmaintained wiki rots. One practitioner maintaining wikis across six projects reports the whole habit costs $10-20 a month in agent fees, with a $0.50 budget cap per automated run (HackerNoon, 2026). Cheap insurance.
You: Lint the wikiClaude runs the four checks from your schema: broken wiki-links, orphan pages nobody links to, dated claims older than 6 months, and pages that contradict each other, all reported into lint-log.md for you to approve. If you've read our piece on evals as unit tests for your company brain, lint is the same idea pointed at knowledge instead of behavior.
Linting is the step everyone skips. I've watched three friends build LLM Wikis in recent months, and two of them ran zero lints after week one. Their wikis are now roughly 40% stale pages, with contradictions scattered through the rest. The wiki doesn't fail loudly. It degrades quietly.
The failure modes are known now, not hypothetical. Practitioners in the gist's comment thread report two recurring ones: stale literals (an outdated fact sitting on a page gets used silently, with no warning) and harness migrations (a Claude Code or tooling update quietly breaks your capture pipeline until a lint notices the wiki stopped growing). Platformer's build hit the same wall: without source verification in the loop, the wiki confidently hallucinated details (Platformer, 2026). Lint is how you catch all three.
Layer 1: schedule the lint
Don't rely on discipline. Schedule the weekly run, and pick the option that matches where your wiki lives, in order of reliability:
Cloud routine, if your wiki is a git repo. Run
/schedulein Claude Code (or use claude.ai/code/routines), and the lint runs on Anthropic's infrastructure whether your laptop is open or not; each run clones the repo fresh, and the findings arrive as aclaude/-prefixed branch or a pull request you review. Research preview on Pro, Max, Team, and Enterprise plans; minimum interval: one hour (routines docs). The only schedule with no offline failure mode. ⟨what a routine lint run looks like: status, branch or PR, duration⟩ <!-- VERIFY BEFORE PUBLISH: T7 findings -->Desktop scheduled task, if your wiki is a local folder. In Claude Code Desktop: Routines, New routine, Local. In Cowork: the Scheduled sidebar, with the wiki folder set on the task. The folder makes it a local task: it runs on your machine, only while the app is open and the computer is awake (desktop scheduled tasks). Sleep through Friday, and the run is skipped, visibly, in the task's history; when the app next opens, exactly one catch-up run fires for the most recent miss within seven days. Approve permissions once (click Run now, pick "always allow" on each prompt); later runs auto-approve.
The Friday habit. Type the lint prompt yourself. Still valid, and the right way to start until you know what a healthy wiki looks like.
Layer 2: the catch-up in session
A second net for the wiki that missed its schedule anyway: a 7-day staleness check that lints at the start of the next session. In Claude Code, this is a SessionStart hook. The script always runs (it takes about 10 milliseconds); whether Claude acts on its output is the part we measured.
.claude/settings.jsonIn the wiki folder:
json
{
  "hooks": {
    "SessionStart": [
      {
        "hooks": [
          { "type": "command", "command": "sh \"$CLAUDE_PROJECT_DIR\"/.claude/hooks/lint-staleness.sh" }
        ]
      }
    ]
  }
}.claude/hooks/lint-staleness.sh:
sh
#!/bin/sh
# Emits a lint instruction into context when the last lint is older than 7 days.
LOG="${CLAUDE_PROJECT_DIR:-.}/lint-log.md"
[ -f "$LOG" ] || { echo "lint-log.md missing: run the wiki lint now and create it."; exit 0; }
LAST=$(grep -m1 '^Last lint:' "$LOG" | sed 's/Last lint: *//')
LAST_TS=$(date -j -f "%Y-%m-%d" "$LAST" +%s 2>/dev/null || date -d "$LAST" +%s 2>/dev/null)
NOW_TS=$(date +%s)
[ -z "$LAST_TS" ] && { echo "lint-log.md has no readable date: run the wiki lint now."; exit 0; }
AGE_DAYS=$(( (NOW_TS - LAST_TS) / 86400 ))
if [ "$AGE_DAYS" -gt 7 ]; then
  echo "The wiki lint is $AGE_DAYS days old. Run the wiki lint first (broken wiki-links, orphans, stale dated claims, contradictions), write findings to lint-log.md, then continue with the user's request."
fi
The script reads the Last lint: date at the top of lint-log.md; when it's older than 7 days, its output tells Claude to run the lint before anything else. With no matcher set, the hook also fires on resume, clear, fork, and compaction, so a stale wiki re-nags after a long session; that's intended. The first time you open a folder carrying a project-level .claude/settings.jsonClaude Code shows a one-time workspace-trust prompt; that's the hook being disclosed, not an error. In our testing, Claude acted on the staleness instruction in ⟨N of 5⟩ cold sessions. <!-- MEASURE BEFORE PUBLISH: T5 findings -->
What does a lint run cost? In our runs, linting a ⟨N⟩-page wiki cost about ⟨$X⟩ in API-equivalent tokens per run (a client-side estimate; on a Pro or Max plan it draws from your subscription, not your card). <!-- MEASURE BEFORE PUBLISH: T6 median and the delta over a no-lint session. -->
Two things we deliberately did not build. No shutdown hooks: a lint is an LLM job that needs minutes, and shutdown gives it none; anything hooked to shutdown fails silently. And no clever catch-up logic of our own: the app's built-in catch-up covers missed schedules, and the lint is idempotent, reading the whole wiki every run, so a missed week costs nothing.
One more maintenance note for 2026 setups: if you've packaged wiki operations as skills, Claude Code's /skill-doctor (v2.1.261+) audits what they cost you in context per session. Run it when the wiki folder starts feeling slow to open.
Our own PromptMetrics wiki is ⟨N⟩ months old as of this update: ⟨N⟩ pages across ⟨N⟩ ingests, lint catching ⟨N⟩ issues over that period (⟨top issue type⟩ leading), at a total agent cost of about ⟨EUR N⟩ a month. What actually broke for us: ⟨one-line honest account⟩.
No Terminal? Build It in Claude Cowork
Everything above works without a terminal. If you're a RevOps manager or CS lead who has never run mkdir and never wants to, Claude Cowork on desktop runs the same pattern: Claude reads from and writes to a local folder you connect to directly, no uploads or downloads (Claude Cowork getting-started guide).
The step mapping:
Scaffold: connect a folder in the Cowork desktop app and ask Claude to create the wiki structure from this guide. It writes the folders, the index, and the schema for you.
Schema: ⟨pending T0: either "Cowork reads the folder's CLAUDE.md directly, so the schema above just works" or "paste the schema into the folder's instructions: Customize, then Folder instructions"⟩. Either way, folder instructions add project context to every session in the folder, and Claude can update them itself as the wiki's rules evolve (Cowork getting-started guide).
Ingest: "add this to the wiki," with a pasted link, a dropped file, or a forwarded email export.
Query: ask in any task with the folder connected.
Lint, layer 1: a scheduled task ("every Friday at 9:00, lint the wiki") with the wiki folder set on it. The folder is what makes it a local task: it runs on your machine, only while the app is open and the computer is awake, and the fine print below covers the rest.
Lint, layer 2: the staleness check goes into the folder instructions in plain language: "at the start of any session in this folder, read the date at the top of lint-log.md; if it's older than 7 days, run the lint first."
The fine print, from testing
What follows combines the documented behavior with our own test numbers. Creating the scheduled lint asks you to trust the folder and approve the task's tool permissions once; in our run, the prompts read ⟨T1 approval wording, verbatim⟩, and later runs auto-approved. When your Mac is asleep, or the app is closed at fire time, the run is skipped and marked as skipped in the task's history; on the next app open or wake, exactly one catch-up run fires for the most recent miss within seven days (desktop scheduled tasks). A missed Friday catches itself up. The staleness check is the second net: in our tests it fired in ⟨N of 5⟩ fresh sessions opened past the 7-day threshold, with ⟨0 of 3⟩ false fires when the lint was current.
One thing the docs won't tell you: folder instructions are context, not enforcement. A Claude Code hook always runs; a folder instruction is a strong default that the numbers above quantify. For a knowledge base, that trade is fine, and the weekly schedule is the backstop either way.
This is also where a small team should start rather than finish. If the wiki proves out and you want it wired into the tools your team actually lives in, that's a First Skill Sprint shaped problem.
Troubleshooting
Problem | Symptom | Fix |
|---|---|---|
Claude ignores the schema | Agent doesn't follow ingest/query/lint workflows | Make sure CLAUDE.md is in the wiki root, and you start Claude Code from that directory (in Cowork: the schema is in the folder instructions) |
Too many pages created per ingest | 20+ new pages for a short article; most are noise | Add "create pages only for significant entities and concepts" to the schema's ingest workflow |
Wikilinks point to nonexistent pages | Broken references accumulating | Run lint more often. The schema catches these |
Index.md grows unreadable | Pages listed but not findable | Group entries in index.md by category with brief one-liners. The schema already does this |
Token costs surprise you | First ingest burns more tokens than expected | Normal. First ingest is the most expensive. After that, updates touch 3 to 5 pages instead of 10 to 15 |
Wiki pages contradict each other | Two pages say different things about the same topic | This is exactly what lint catches. Run it and let Claude reconcile |
Wiki stopped growing after an update | Ingests silently do less than before | A harness migration broke the pipeline. Lint surfaces it; re-check the schema against the current Claude Code version |
FAQ
Is this just RAG with extra steps?
No, it's RAG with fewer steps and less infrastructure. RAG retrieves document chunks at query time and re-reads them on every question, which requires a vector database, an embedding model, and a retrieval layer you maintain. An LLM Wiki reads sources once during ingest and writes permanent markdown pages; queries read the pre-compiled pages. The trade-off is a scale ceiling in the tens of thousands of compiled tokens (see "Where the pattern tops out" above), which personal and team wikis rarely reach.
Do I need Obsidian or a specific tool?
You don't need anything beyond a text editor and Claude Code, or Claude Cowork with a connected folder. The wiki is a folder of markdown files. That said, Obsidian's graph view is a nice way to visualize the wiki as it grows [[wikilink]] syntax is native there, and the community has already shipped an Obsidian plugin for the Karpathy wiki pattern.
How is this different from Claude Code's auto memory?
Auto memory, on by default since 2026, is Claude's own machine-local notebook: a per-repo MEMORY.md index plus topic files, curated by Claude, never checked into git and not shared across machines (Claude Code memory docs). The LLM Wiki is the shared, versioned, human-reviewed layer your whole team (and any other agent) can use. They compose: auto memory for personal working preferences, the wiki for institutional knowledge.
What happens when my wiki gets big?
The index.md pattern handles scale: Claude reads the index to find relevant pages instead of loading every page. Platformer's wiki runs 1,440+ pages on this structure (Platformer, 2026). Past the ceiling discussed in "Where the pattern tops out," split into topic-specific wikis or consider retrieval infrastructure.
Can I use this with a team?
Yes: a shared git repo with the CLAUDE.md schema works for most teams, and it's the reason the wiki beats auto memory for shared knowledge (auto memory stays on each person's machine by design). Assign one owner for the weekly lint, review wiki changes like code, and let everyone ingest. Larger teams that outgrow a single repo usually split into per-domain wikis before they need graph databases.
Next Steps
53% of developers say waiting for answers disrupts their workflow (Stack Overflow, 2024). Your LLM Wiki eliminates that wait for questions you've already answered.
Ingest three more sources this week. Choose things you'd normally bookmark and forget about. Watch the wiki compound. Run lint every Friday, or let the schedule do it and let the hook catch what the schedule missed.
When you're ready to level up, wire in an Obsidian MCP server so your agent can read and write to your vault directly; the MCP ecosystem your wiki plugs into keeps growing, with the Glama registry alone indexing 85,000+ open-source servers (Glama, retrieved 2026-09-11). Then build agent skills that use the wiki as a knowledge base rather than relying on web search or training-data cutoffs.
The wiki gets more useful every time you feed it. Start now.